
"Is the assistant better than last month?" It is what leadership asks after every prompt change, and the answer tends to be "I'd say so". Nobody can say what they would have had to see on screen to answer no.
I propose calling it an unwritten standard: accepting an AI's behaviour because it looks good to whoever is watching, without having written down beforehand what counts as a failure.
Unwritten standard: deciding that an AI works or has improved because of the impression of whoever is watching, without a written list of what counts as a failure and what is accepted.
The thesis
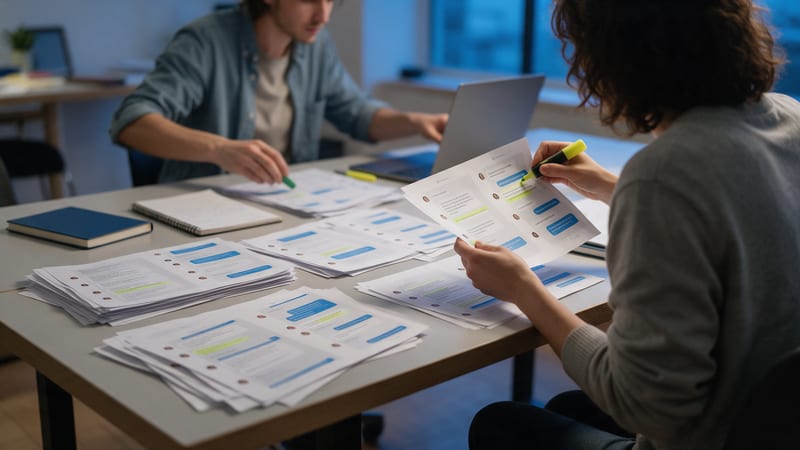
I am not saying you need to build an evaluation platform or start with a metrics dashboard; I am saying the first step is for two people on the team to read dozens of real outputs together and write down what fails and how serious it is. The metric comes out of that reading, and whoever defines it is whoever knows the product. That is how a team leaves the unwritten standard behind.
An evaluation (an eval) is a repeatable measure of whether what the AI produces is good enough for what your business needs. The hard part of an evaluation is the standard it scores against.
What the data says
Hamel Husain, who helps teams evaluate products built on language models, put it in March 2024: review as much real data as you can, until you stop learning new things, and write small, cheap tests that run on every change. For human ratings he recommends starting with simple good-or-bad labels, and makes clear that the acceptable failure rate is a product decision.
There is a nuance that complicates the easy advice of "write the criteria and measure". Shreya Shankar and her colleagues describe, in a user study published as a preprint in April 2024, criteria drift: we need criteria to score outputs, but scoring them helps us define the criteria, and some only appear when we see what the model writes. It is a qualitative study with no figures, but it explains why criteria are written after reading and revised every time you read again.
Anthropic, in its engineering guide to evaluating agents (January 9, 2026), suggests starting with 20 to 50 tasks drawn from real failures and notes that many teams wait to have hundreds without needing them. It also tells a useful case: a model scored 42% on a benchmark until a researcher found that the grading was too rigid (it rejected 96.12 when the expected answer was 96.124991…), that some task descriptions were ambiguous and that some tasks could not be reproduced. Once that was fixed, the score rose to 95%. The lesson is that the measure itself can be wrong.
Consistency counts too. The τ-bench benchmark (Yao and colleagues, June 2024) measured tool-using agents in simulated customer-service conversations: the most advanced agents of the time, such as gpt-4o, solved fewer than 50% of the tasks and, when each task was repeated eight times, got all eight right in fewer than 25% of the retail ones. Three good examples in a demo say little about what will happen the fourth time.
Automated judges, a model that scores another model's answers, have their own trap. Husain warns, in his October 2024 guide updated in September 2026, that the percentage of agreement with a person misleads when failures are rare: a judge that always said "correct" would agree with the person 95% of the time on a system that is right 95% of the time (the arithmetic is ours). That is why he asks for a domain expert, pass-or-fail decisions with a written critique, and measuring separately how many passes and how many failures the judge catches. OpenAI's evaluation documentation (no visible date, accessed November 16, 2026) lists "vibe-based evals" among its anti-patterns, accepting something because "it seems like it's working", and recommends widening a judge only once it agrees consistently with human annotations.
The limits: Husain, Anthropic and OpenAI speak from their practice and documentation; τ-bench uses simulated scenarios with 2024 models, and Shankar's work is qualitative. None of these sources is a controlled study of your company's assistant.
What shows up in meetings
- The prompt is changed and tested with the three questions everyone remembers from the last meeting.
- The quality report is the average of the scores from a judge model that nobody has compared with a person's opinion.
- Two people read the same answer, one calls it good and the other bad, and the more senior one prevails.
- Each customer complaint is fixed on its own, and nobody checks whether the fix breaks an answer that was already working.
- After switching models, someone says it "performs the same", and nobody knows what was looked at to say so.
Why it is understandable
Writing down what a failure is forces a discussion, and having that discussion with a delivery looming is the last thing anyone wants. Demos convince, and tools offer ready-made scores that feel rigorous. And for years software has been tested with tests that say green or red. With language models that comfort ends: there are many acceptable answers and someone has to decide which.
Timing matters too. A team that has just put its first assistant into production has visible work in front of it, with a date, and evaluations are invisible work: nobody notices them until they are missing. It makes sense that they lose out to the next feature.
Part of the responsibility lies with leadership. If every review rewards the best demo and nobody asks to see the twenty worst cases of the week, the team does what it is asked: it shows what shines.
What is lost without a written standard
Without a written standard, every prompt change is a bet: nobody can say whether it improves the case that worries you and worsens another. The team spends weeks tuning against its own impression and finds out about failures when customers notice them. An unvalidated automated judge scores well what sounds good, and the metric ends up confirming what the team already thought. And because the standard lives in the heads of two or three people, it leaves with them when they move to another project.
There is a quieter cost. When the serious complaint finally arrives, the team has no earlier cases to reproduce it and no standard to decide whether it is an isolated failure or a type of failure that has been there for months.
What to do
If you lead the team:
- Name a business person who decides what "good" means for this product and give them an hour a week, for a month, to read real outputs alongside engineering. Teresa Torres, who writes for product teams, puts it this way in her September 2026 guide: correctness depends on context, and a vendor should not be the one defining it for your product.
- Ask in every review for the twenty worst real cases of the week, as well as the best ones.
- Keep the criteria and the cases in the repository, next to the team's context (its rules and its product knowledge), and have them run on their own on every change of prompt, model or tools: no change gets in without passing them. When someone proposes switching models, ask for the same set of cases run with the current model and the new one before deciding.
- Agree with the team, for each type of failure, the rate you accept and review it every quarter. It is a product decision.
If you do the work:
- Do the error analysis first. Read between 50 and 100 real outputs (our rough figure), note in one line what fails in each and group them by type. Stop when twenty readings in a row bring no new type (our rough criterion).
- Turn each frequent type into a yes-or-no question, with one example that passes and one that fails ("does it quote a price that is not in the context?"). Use the automated judge only for what cannot be checked with code.
- Validate the automated judge before trusting it: label a set by hand with someone who knows the domain, measure separately which failures it catches and which passes it respects, give it an "I don't know" output and do not widen its use until it agrees.
- Bring it into the development cycle. The agreed criterion goes in as an acceptance criterion of the specification in Spec-Driven Development (SDD: the specification, with checkable criteria, is approved before any code is written), so that the specification is already an eval, and every failure that arrives from production becomes a new regression case. Run each case several times to check that the result repeats, and read outputs again whenever the criteria change. To tell whether a change really improves things you also need a rubric and a point of comparison.
I have seen how hard it is to define the standard for what "good" or "better" means in a team of educators reviewing a training assistant, or to define the rubric for judging whether one answer to a tender is better than the previous one in Licia, onext's tender assistant. That is why we have implemented LLMOps, a workflow for the agentic layer of our projects based on setting rubrics, golden sets (sets of reference cases), mutations (variants of each case to see whether the result holds up) and evaluations.
Writing down what counts as a failure is what takes a team out of the unwritten standard, and whoever knows the product decides it.
Frequently asked questions
What is an AI eval?
It is a repeatable measure of whether what the AI produces is good enough for what your business needs. It can be a check written in code, an automated judge or a person scoring. The hard part is deciding what standard it scores against.
What is error analysis in a system that uses AI?
It means reading real outputs from the system, noting in one line what fails in each, and grouping the failures by type. That list gives you the criteria worth measuring, and also the ones that are not.
How many examples do you need to start?
Fewer than people tend to think. Anthropic's January 2026 engineering guide suggests starting with 20 to 50 tasks drawn from real failures and warns that many teams wait until they have hundreds without needing to.
Why yes-or-no criteria rather than a scale from 1 to 5?
Hamel Husain recommends starting with simple good-or-bad labels, and in his guide to judges he asks for clear pass-or-fail decisions with a written critique. They force a decision and can be checked against what a person thinks.
Can you trust a model that scores another model?
Only after validating it. Label a set by hand with someone who knows the domain, measure separately which failures it catches and which passes it respects, and do not widen its use until it agrees consistently with people.
What is pass^k and why does it matter?
It is the probability of getting a task right all k times it is repeated. Anthropic gives an example: with a 75% success rate per attempt, succeeding three times in a row is about 42%, because it is 0.75 cubed. That is why each case is run several times.
Sources
- Hamel Husain, «Your AI Product Needs Evals», March 29, 2024.
- Shreya Shankar, J.D. Zamfirescu-Pereira, Björn Hartmann, Aditya G. Parameswaran and Ian Arawjo, «Who Validates the Validators? Aligning LLM-Assisted Evaluation of LLM Outputs with Human Preferences», arXiv 2404.12272, April 18, 2024.
- Hamel Husain, «Using LLM-as-a-Judge For Evaluation: A Complete Guide», October 29, 2024, updated September 1, 2026.
- Anthropic, «Demystifying evals for AI agents», January 9, 2026.
- Shunyu Yao, Noah Shinn, Pedram Razavi and Karthik Narasimhan, «τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains», arXiv 2406.12045, June 17, 2024.
- OpenAI, «Evaluation best practices», developer documentation, no visible publication date; accessed November 16, 2026.
- Teresa Torres, «AI Evals: A Hands-On Guide for Product Teams», Product Talk, September 2, 2026.
Bernat López is founder and CEO of onext, an AI boutique. He helps development and product teams work with AI with method —specification before building, automated checks and Spec-Driven Development— and applies to his own company what he proposes: onext runs on its own agentic system.
LinkedIn →